
The Price of Proof · Part I · A companion to The Assurance Gap
What happens to an economy when AI agents join the workforce? The work does not vanish. It changes shape. Generation is getting cheap; certifying what was generated is now the largest line in the bill, and the people who do the certifying are the new centre of the labour market.
Disclosure: I co-authored IMDA Singapore’s Model AI Governance Framework for Agentic AI, and I have a commercial interest in TrustOS runtime governance. Both bear on the argument below; I declare them so you can weigh it.
Read this at two depths. Sections I to III give the argument in ten minutes. Sections IV to X give the evidence, the panel, Singapore, the strongest objections and five numbers to ask for. The library at the end shows how closely each source was read.
I. The Onboarding Agent
Start with a bank account, because it is the most ordinary thing an agent can open. In August 2026 McKinsey’s QuantumBlack published a worked example of a fully agentic customer-onboarding workflow at a bank. It is not one agent. It is five to seven agents, several deterministic systems that do the parts no one wants left to probability, and two to four teams of people providing oversight. Between 10 and 20 per cent of runs are expected to go to risk and functional experts for review. The fully loaded cost of onboarding a customer falls from somewhere between $50 and $150 to between $10 and $30.
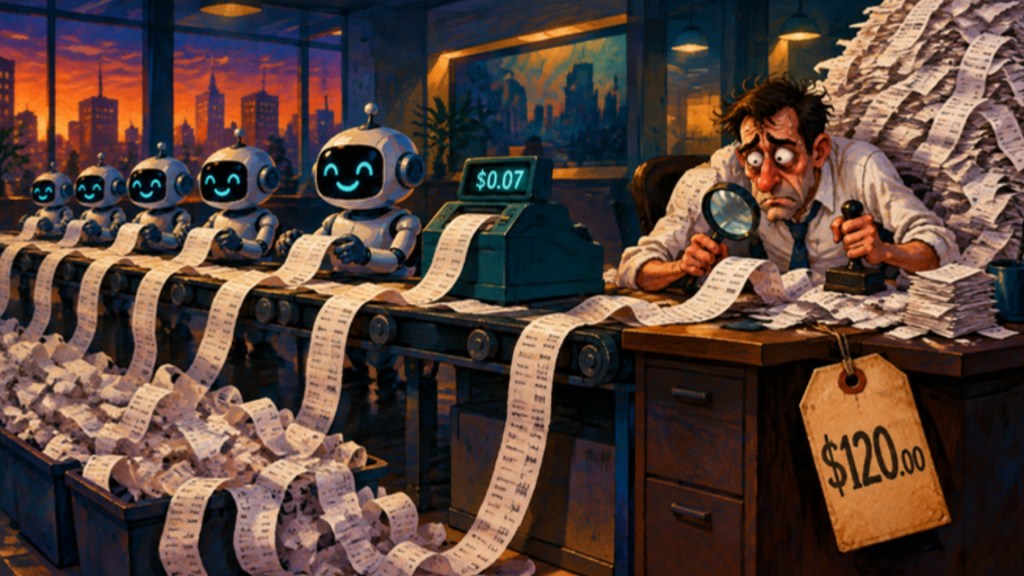
That is a large saving, and it is the number that will be quoted in board papers. The more interesting number is buried in a different example in the same paper. In a banking customer-service agent, McKinsey estimates that tokens, the raw cost of the model thinking and writing, make up about 20 to 25 per cent of variable running cost. Human oversight makes up about 70 to 75 per cent.
Read that again, because it inverts the story most people tell about AI and work. The machine is the cheap part. The expensive part is the person who checks it. The receipt costs more than the agent.
II. What Happens When Agents Join the Workforce
There are two familiar answers to the question in this essay’s subtitle, and both are incomplete.
The first is the spiral. In February 2026 a scenario from Citrini Research travelled fast enough to get its own TechCrunch explainer: agents improve, firms need fewer white-collar workers, displaced workers spend less, margins tighten, firms invest more in agents to protect them, and the loop turns again. It is a bear case built not on rogue AI but on the slow unspooling of demand.
The second is the reassurance. New technologies destroy tasks, not work; the lump-of-labour fallacy has been wrong for two centuries; productivity rises and new occupations appear. Payden’s “Intelligence on Tap” put the optimistic case well this year: agents as a scalable pool of junior analysts, making existing workers more productive.
Both stories assume the same thing: that once an agent can do a task, the task is done. The evidence of 2026 says otherwise. When agents join the workforce, a new job appears beside every task they take, and it is not optional. Someone has to decide whether the output is right, whether the action was authorised, and who pays if it was not. That job is verification. It is the 70 to 75 per cent. And it is where the economics of the agent age will be decided.
The early data on how agents are actually used points the same way. Anthropic’s Economic Index has reported that conversations on its consumer product lean towards augmentation, people working with the model, while traffic through its programming interface, where businesses wire models into their own systems, is dominated by automation, the model doing the task. Augmentation keeps a human in the loop by design. Automation moves the human to the end of the line, as the person who signs. The shift from the first to the second is the shift this essay is about.
III. The Bill, Line by Line
If proof is the cost, it should show up in every honest costing of an agent. It does.
| Cost line | What the evidence says | Source |
|---|---|---|
| Model tokens | About 20 to 25% of variable run cost in a banking service agent | McKinsey QuantumBlack, Aug 2026 |
| Human oversight | About 70 to 75% of variable run cost in the same example; 10 to 20% of onboarding runs reviewed | McKinsey QuantumBlack, Aug 2026 |
| Machine self-checking | About 60% of an agentic task’s cost spent on the agent checking, repairing and re-verifying its own work | McKinsey, “Is that AI agent worth it?”, Jul 2026 |
| Total enterprise cost | Roughly three times the token invoice once subscriptions, platform, governance, change and expected failure are counted (a modelled estimate) | EY, “Agentic AI ROI”, Sep 2026 |
| Lifetime cost | Operation, maintenance and enrichment put at 60 to 80% of a system’s lifetime cost | Oliver Wyman, Jul 2026 (secondary) |
| Rework | Nearly 40% of the time AI saves is lost to rework; 77% of daily users review AI output as carefully as human work | Workday, Jan 2026 (n=3,200) |
Three things stand out. First, the line that falls fastest, tokens, is the smallest. Second, the line that does not fall, people checking, is the largest. Third, even the machine spends most of its effort checking itself. Verification is not a tax on the agent economy. It is most of the agent economy.
IV. The Jevons Trap
The obvious objection is that all of this will get cheaper. Part of it will. Epoch AI finds that the price of reaching a fixed level of model performance has been falling at a median of about 50 times a year across benchmarks, with a range from roughly 9 to 900 times depending on the task. No input in economic history has fallen in price that fast.
And yet total bills are rising. In 1865 William Stanley Jevons noticed that more efficient steam engines increased Britain’s coal consumption rather than reducing it, because cheaper power found new uses faster than efficiency saved fuel. The token economy has followed the script. Uber’s chief technology officer told The Information in April that the company had exhausted its 2026 budget for AI coding tools in four months. Microsoft cancelled most of its engineers’ direct Claude Code licences in May, according to The Verge. A McKinsey survey of firms tracking AI operations costs found 93 per cent over budget, though the sample was small (75 respondents).
Here is the part the cost dashboards miss. Every additional token generated is an additional claim that someone may need to verify. If output volume rises faster than the price of generating it falls, the volume needing proof rises too. Accenture’s October 2026 tokenomics study found that only about 20 cents of every dollar spent on tokens is tied to a quantified financial outcome. Deloitte’s October 2026 survey found that 71 per cent of firms track total inference spend, but only 44 per cent track the cost of a unit of work. Firms are metering generation and guessing at proof. That is the Jevons trap: cheaper thinking, more output, a larger and largely unpriced verification bill.
V. The Verify-to-Do Ratio
If verification is the cost, the ratio that decides whether an agent pays is not accuracy. It is how long it takes to check the work compared with how long it takes to do it.
McKinsey made the point with a striking example at a September 2026 session reported by Fortune: an agent that succeeds only a little over 10 per cent of the time can still create value, if a human can verify its output in about six minutes against an hour to do the task. Low accuracy plus cheap checking can beat high accuracy plus expensive checking. That is the most important sentence in agent economics, and almost no procurement process is built around it.
A worked illustration makes the arithmetic plain. The figures below are hypothetical, chosen only to show the shape.
| Workflow | Human time to do | Human time to verify | Agent success rate | Verdict |
|---|---|---|---|---|
| Draft a standard customer reply | 10 minutes | 1 minute | 80% | Pays easily: checking is a tenth of doing |
| Reconcile a supplier invoice | 20 minutes | 5 minutes | 60% | Pays if failures are caught and cheap to redo |
| Write a credit memo | 3 hours | 90 minutes | 70% | Marginal: verification is half the original work |
| Change production code in a large, familiar codebase | 1 hour | 50 minutes | Varies | Can be negative: checking approaches doing |
| Release a held payment | 5 minutes | 5 minutes, plus liability | High | Proof, not speed, is the product |
The bottom rows are not hypothetical worries. In July 2025, METR ran a randomised trial with 16 experienced open-source developers working on 246 real issues in repositories they knew well. With AI tools allowed, they took 19 per cent longer; afterwards, they believed they had been about 20 per cent faster. METR expects larger gains for less experienced developers and less familiar code, and other trials have found gains. But the result shows what happens when verification costs approach doing costs: the benefit can vanish while the felt benefit remains.
Chains make it worse. If each step of an agent workflow is right 95 per cent of the time, a three-step chain finishes cleanly about 86 per cent of the time, a ten-step chain about 60 per cent, and a twenty-step chain about 36 per cent. That is arithmetic, not measurement, but measurement agrees: a NeurIPS 2025 study of 1,642 multi-agent traces across seven frameworks (Cemri et al.) found failure rates between 41 and 87 per cent. Every handoff is another place where proof is needed. METR’s time-horizon work points the same way: the length of task an agent can complete half the time has been doubling roughly every seven months, but the length it can complete reliably, four times out of five, is several times shorter. The gap between “can” and “can be trusted to” is exactly where verification lives.
VI. The New Shape of a Job
So what happens to the workforce? The honest answer is that the remaining human work concentrates in three activities: judgement, exception handling and accountability. These are the most expensive tasks to staff and the hardest to automate. They are also, increasingly, the job.
That has three consequences that the spiral and the reassurance both miss.
First, oversight design is a wage-setting decision. David Autor and Neil Thompson’s 2025 paper “Expertise” shows that whether automation raises or lowers the value of remaining work depends on whether it removes the inexpert or the expert part of a job. Remove the routine tasks and the remaining work demands more expertise: wages rise and headcount falls, as with accounting clerks between 1980 and 2018. Remove the expert tasks and the remaining work demands less: wages fall and headcount rises, as with inventory clerks. An agent deployment that leaves people as rubber stamps is choosing the second path. One that leaves them owning the judgement is choosing the first. Most firms are making this choice without knowing they are making it.
Second, the apprenticeship ladder is losing its bottom rungs. Verification requires expertise, and expertise has traditionally been built by doing the routine work that agents now take. Brynjolfsson, Chandar and Chen’s “Canaries in the Coal Mine?” analysis of US payroll data found that employment for workers aged 22 to 25 in the most AI-exposed occupations fell markedly against the trend after late 2022, mainly through reduced hiring rather than layoffs, while older workers in the same occupations held up. The paradox is sharp: the economy needs more expert checkers and is training fewer people who could become them. A company that removes every junior task today may find, in five years, that nobody in the building can tell a good agent output from a plausible one.
Third, cheap checking is not the same as checking. The temptation, once oversight is 70 per cent of the bill, is to make it nominal. The evidence on nominal oversight is grim. In a European Commission Joint Research Centre experiment with 1,411 HR and banking professionals, overseers followed a biased AI recommendation as readily as a fair one. Stanford and BetterUp found that about 40 per cent of US desk workers had received AI “workslop” in the previous month, costing an estimated $186 per worker per month to clean up. And Klarna, which said in early 2024 that its assistant was doing the work of about 700 customer-service agents, said in 2025 that a cost-led approach had lowered quality and began hiring people back. Removing the checker does not remove the cost of checking. It moves it to the customer, the colleague or the balance sheet. That is the subject of Part II.
VII. The Panel: Four Rooms on the Checking Economy
As in this series’ earlier essays, I put the same question to four rooms that do not usually talk to each other: academia, government, the labs and the advisers. The question was simple: when agents join the workforce, who pays for the proof?
Academia answered with a theory and a warning. Christian Catalini, Xiang Hui and Jane Wu’s February 2026 paper, “Some Simple Economics of AGI”, makes the cleanest version of this essay’s argument: the cost of automation falls exponentially, but verification is bounded by human attention, so value shifts to whoever can provide trusted verification and underwrite it. Daron Acemoglu’s task-based arithmetic supplies the warning. Only a minority of tasks are both exposed to AI and profitable to automate, which is why his estimate of the productivity gain over a decade is modest. The filter is not what agents can do; it is what is profitable once everything, including checking, is counted.
Government answered with a word: nominal. The US Office of the Comptroller of the Currency, in its November 2026 examiner framework for banks’ use of advanced AI, asks examiners to look at whether human approval is more than a click. NIST’s October 2026 design tenets for agent identity warn that human-in-the-loop review can become so frequent that it degrades into habitual approval. Singapore’s agentic governance framework, which I co-authored, asks organisations to put checkpoints on irreversible actions and to audit whether oversight remains effective over time. Three governments, one worry: oversight that exists on paper and not in practice.
The labs answered with restraint. Anthropic’s guidance on building agents tells developers to start with the simplest solution and add agents only when needed, and its later guidance found that a single agent with the right skills often beats a team of sub-agents on quality, cost and speed. Its own multi-agent research system used about fifteen times the tokens of a chat. Microsoft, after its coding-tool costs overran, told staff it was optimising for impact per token rather than fewer tokens. The labs are telling buyers, in effect, that more agents mean more proof, and proof is not free.
The advisers answered with the budget. McKinsey says to budget for gateways, AgentOps, monitoring, compliance checks, model approvals and remediation, and that redesigning a workflow to reduce exceptions matters more than choosing a model. EY counts governance, organisational change and expected failure as separate cost lines. BCG reports that firms with all six of its agent controls in place see about three times the agentic AI value of firms with one, and that only about 5 per cent have all six enterprise-wide. Commonwealth Bank of Australia’s chief executive, Matt Comyn, observed in June that rising AI costs might at least curb low-value output. The advisers’ consensus is blunt: governance is not overhead on value. It is the condition of it.
Where do the rooms disagree? On who should pay. Academia says the verifier will capture the value. Government says the deployer must carry the accountability. The labs say the builder should keep systems simple. The advisers say the buyer must budget for it. Nobody yet says the consumer or the worker should, and yet, as Part II will show, they are often the ones who do.
VIII. Singapore: The Two-Speed Checking Economy
Singapore is a useful test case because it has the infrastructure for proof and a visible gap in who can afford it.
IMDA’s Singapore Digital Economy Report 2026, released in October, reports that AI adoption among SMEs rose from 14.5 to 23.4 per cent, while large local enterprises rose from 62.5 to 70.4 per cent. A Ministry of Manpower report in April found adoption of about 24 per cent among firms with fewer than 25 employees and about 76 per cent among firms with more than 500, with high implementation costs cited as a constraint by about 45 per cent. (Both figures come from secondary reports of the publications; check the originals before quoting.)
Why does the gap persist when tools are cheap? Because the fixed costs of proof do not scale down. In McKinsey’s onboarding example, doubling volume from 2,500 customers a year adds only about $5,000 in cost, because the orchestration, monitoring and review capacity are already paid for. A large bank spreads that fixed assurance cost across millions of transactions. A twenty-person firm cannot spread one reviewer’s salary across anything. Cheap generation plus expensive proof is a recipe for a two-speed economy, in which large firms automate safely and small firms either do not automate or automate without checking.
Singapore’s answer, deliberately or not, is to make proof shared infrastructure: the AI Verify testing toolkit, an accreditation programme for private-sector AI testers, the agentic governance framework, and MAS’s industry-built SAFR runtime framework, discussed in The Assurance Gap. If assurance is provided as a public good, or at least as a shared utility, small firms can buy proof by the transaction instead of building it. That is the policy question for every economy that wants agents to raise productivity broadly rather than concentrate it.
IX. The Strongest Objections
“AI will verify AI, so human attention stops being the bottleneck.” Partly true, and already happening: McKinsey’s 60 per cent is machine self-checking, and certification firms such as AIUC test agents with agents, with humans signing the final audit. But a machine check is only proof if someone trusts the checker and someone will pay when it is wrong. The bottleneck moves from attention to accountability. It does not disappear.
“Agents are already paying off.” Many are. Wharton and GBK found three in four enterprise leaders reporting positive returns from generative AI, and the widely quoted MIT finding that 95 per cent of firms see no return rests on a contested method. This essay does not claim agents fail. It claims that their returns are rarely costed with assurance included, which is why so many surprise their owners.
“Oversight costs will fall as agents get more reliable.” Some will. McKinsey’s own advice is that reducing exception rates through workflow redesign is the lever. But reliability gains are offset by volume (the Jevons trap) and by the length of tasks agents are trusted with. A more reliable agent is given longer chains and larger authority, which raises the stakes of each remaining check.
“This is a consultant’s argument for more consulting.” A fair suspicion, and I declare my own interests above. The test is whether the evidence holds without the advisers. It does: the METR trial, the JRC experiment, the payroll data and the token arithmetic are independent of anyone selling assurance.
X. Five Numbers Every CFO Should Ask For
If the receipt costs more than the agent, the receipt is what management should measure. Before approving the next agent deployment, ask for five numbers.
- Cost per verified, completed task, including retries, review and rework, not cost per token or per run.
- Review share: what proportion of runs a human examines, and how long each review takes.
- Verify-to-do ratio: minutes to check against minutes to do, by workflow.
- Exception and rework rate, and the trend in each since launch.
- Who holds the loss when a verified output turns out to be wrong: the firm, the vendor, the insurer, the customer or the employee who clicked approve.
A deployment that cannot produce these five numbers is not cheaper than it looks. It is unpriced.
Coda: Where the Jobs Went
So, what happens to an economy when AI agents join the workforce? The tasks move to the machines. The judgement, the exceptions and the accountability stay with people, and they become the most valuable and most expensive work in the building. Whether that produces an augmented economy or a hollow one depends on a choice most firms are making by default: whether the human beside the agent is an expert who owns the outcome or a clerk who clicks approve.
The receipt costs more than the agent. The firms, and the economies, that learn to produce receipts cheaply and honestly will capture the gains. Those that fake them will discover, in Part II, what a discount on proof really costs.
Next in The Price of Proof: Part II, The Rubber-Stamp Discount.
Library: sources and how closely each was read
“Read” means the page was read for this essay; “secondary” means the figure was taken from a report of the source; “the author’s research” means the author’s own research file of November 2026. Check primaries before quoting.
Costs and economics of agents
- McKinsey QuantumBlack, “Where AI agents pay off: a practical guide to the economics of agentic workflows” (24 Aug 2026). Read in full in the author’s research. Illustrative benchmarks from engagements, not audited costs.
- McKinsey, “Is that AI agent worth it? Agentic economics and the modern operating model” (Jul 2026), PDF mirror. Read via mirror. Source of the 60% self-checking and 93% over-budget (n=75) figures.
- Fortune, “McKinsey: cheaper AI models, bigger AI bills” (23 Sep 2026). Read. The 10% success, six-minute verification example.
- EY, “Agentic AI ROI: Can AI pay for itself?” (Sep 2026). Read in full in the author’s research. Modelled, not measured.
- Workday, “Companies are leaving AI gains on the table” (14 Jan 2026). Read. n=3,200.
- Epoch AI, LLM inference price trends. Read.
- Accenture, “The CIO’s Guide to AI Tokenomics” (Oct 2026); Deloitte, State of AI in the Enterprise (Oct 2026); Oliver Wyman CIO and CEO surveys (Jul 2026). From the author’s research file; secondary. Check primaries before quoting.
- Fortune on Microsoft and AI token costs (22 May 2026). Read. Uber budget via The Information, secondary.
Reliability and the verify-to-do ratio
- METR, randomised trial of early-2025 AI tools on experienced open-source developers (Jul 2025), via InfoWorld. Secondary report of the paper.
- Cemri et al., “Why Do Multi-Agent LLM Systems Fail?” (arXiv 2503.13657; NeurIPS 2025). Abstract and secondary.
- METR, “Measuring AI Ability to Complete Long Tasks” (Mar 2025) and Time Horizon 1.1 (Jan 2026). Secondary.
- Anthropic, “Building Effective Agents” (Dec 2024) and “How we built our multi-agent research system” (Jun 2025). Secondary in the author’s research.
Work, wages and the shape of jobs
- Autor, D. and Thompson, N., “Expertise”, NBER WP 33941 (2025); Journal of the European Economic Association. Abstract and secondary.
- Brynjolfsson, E., Chandar, B. and Chen, R., “Canaries in the Coal Mine?”, Stanford Digital Economy Lab (revised Aug 2026). Secondary. Descriptive, not causal.
- Acemoglu, D., “The Simple Macroeconomics of AI”, NBER WP 32487 (2024); Economic Policy (2025). Secondary.
- Catalini, C., Hui, X. and Wu, J., “Some Simple Economics of AGI” (arXiv 2602.20946, Feb 2026). Read in the author’s research.
- Anthropic Economic Index reports (2025 to 2026). Secondary.
- Stanford Social Media Lab and BetterUp, workslop study (Sep 2025), via Gizmodo. Secondary report.
- European Commission JRC, “The Impact of Human-AI Interaction on Discrimination” (Jan 2025). Read.
- Entrepreneur, “Klarna CEO reverses course by hiring more humans, not AI” (9 May 2025). Read.
The economy-level debate
- TechCrunch, “How AI agents could destroy the economy” (23 Feb 2026), on the Citrini Research scenario. Read in summary.
- Payden, “Intelligence on Tap: The Early Economics of AI Agents” (Jan, updated Mar 2026). Read in summary.
- Wharton and GBK Collective, enterprise GenAI adoption report (Oct 2025). Read.
Governance and Singapore
- OCC Bulletin 2026-54, “Super Intelligence: Supervisory Framework” (4 Nov 2026). Bulletin read in the author’s research; examiner resource only.
- NIST, Design Tenets for Agent Identity Management Systems (27 Oct 2026). Secondary.
- IMDA, Model AI Governance Framework for Agentic AI (Jan 2026), via Allen & Gledhill. Author is a co-author. Read.
- IMDA, Singapore Digital Economy Report 2026 (Oct 2026); Ministry of Manpower AI adoption report (Apr 2026). Secondary reports. Check originals.
- BCG, “The Formula for Agentic AI Value” (Sep 2026). Secondary.
- Reuters via Yahoo Finance, CBA flags surging AI costs and “work slop” (Jun 2026). Read.
Luke Soon is an AI futurist and author of Genesis: Human Experience in the Age of Artificial Intelligence and Synthesis: SuperIntelligence Protocol. He co-authored IMDA Singapore’s Model Governance Framework for Agentic AI.


Leave a Reply